SYVAData Nexus
The private control layer for shared AI inference.
Data Nexus turns model inference into shared AI microservices — governed and delivered across the GPUs and cloud paths you host. Apps keep their logic; the estate shares the models.
- Data Nexus
- Consumers
- GPU node
- CPU node
- Cloud Services
Why it exists
Don't ship a model inside every app.
Private AI needs two layers: application logic, and model inference. Baking them together locks GPUs to one product and multiplies ops.
Without a shared plane
Capacity siloed. Lifecycle repeats. Hard to share across products.
What should happen
call AI microservices
Shared inference · many apps
Models become AI microservices that many products can call. Data Nexus governs and delivers that fabric on your estate.
What you gain
Why Data Nexus is necessary.
Once inference is shared, you still need a self-hosted plane to register, secure, and deliver it. That is the job.
01
GPUs serve the estate
Inference runs as shared services — capacity is pooled, not trapped inside one app.
02
Apps stay on logic
Products call the fabric. They do not each ship, host, and operate a model stack.
03
One governed entry
Keys, scopes, and audit sit in front of private GPUs and approved cloud APIs alike.
04
One plane to operate
Register services, watch health, and route traffic across the estate from a single control layer.
How it works
One layer. Two jobs.
Govern who can use inference, then deliver it across GPUs and approved cloud — on infrastructure you host. Deep architecture stays in a private review.
How the layer works
Self-hosted · on your estate
Apps and partners enter one governed surface. Data Nexus decides what is allowed, then delivers inference across the estate you host.
Secure entry
One door for every AI productAuthenticated access for applications, partners, and operators — without each team inventing its own front door.
↓ two jobs, one platform
Operate & govern
Control
- See every inference service in one place
- Decide who can call what
- Keep a clear record of access and change
Route & serve
Delivery
- Send work to the right capacity
- Keep private GPUs and approved cloud under one path
- Stay fast when apps stream or chat in real time
↓ out to capacity you control
Your estate
Where inference actually runsYour GPUs
Models you run on-prem
Your estate nodes
Health and local control
Approved cloud
When hybrid is the right call
From call to answer
01
Connect
Your app reaches one private surface.
02
Govern
Access and policy are checked first.
03
Deliver
Work goes to the right GPU or cloud path.
04
Prove
Ops and compliance can see what happened.
On the fabric
First applications.
Deployment
Customer-hosted. Always.
Runs on your on-prem servers or private cloud.
Single-site
Platform + inference in one environment.
Distributed cluster
Central hub, GPU workers at the edge.
Hybrid AI
On-prem models + governed cloud connectors.
Inside the console
A look inside the console.
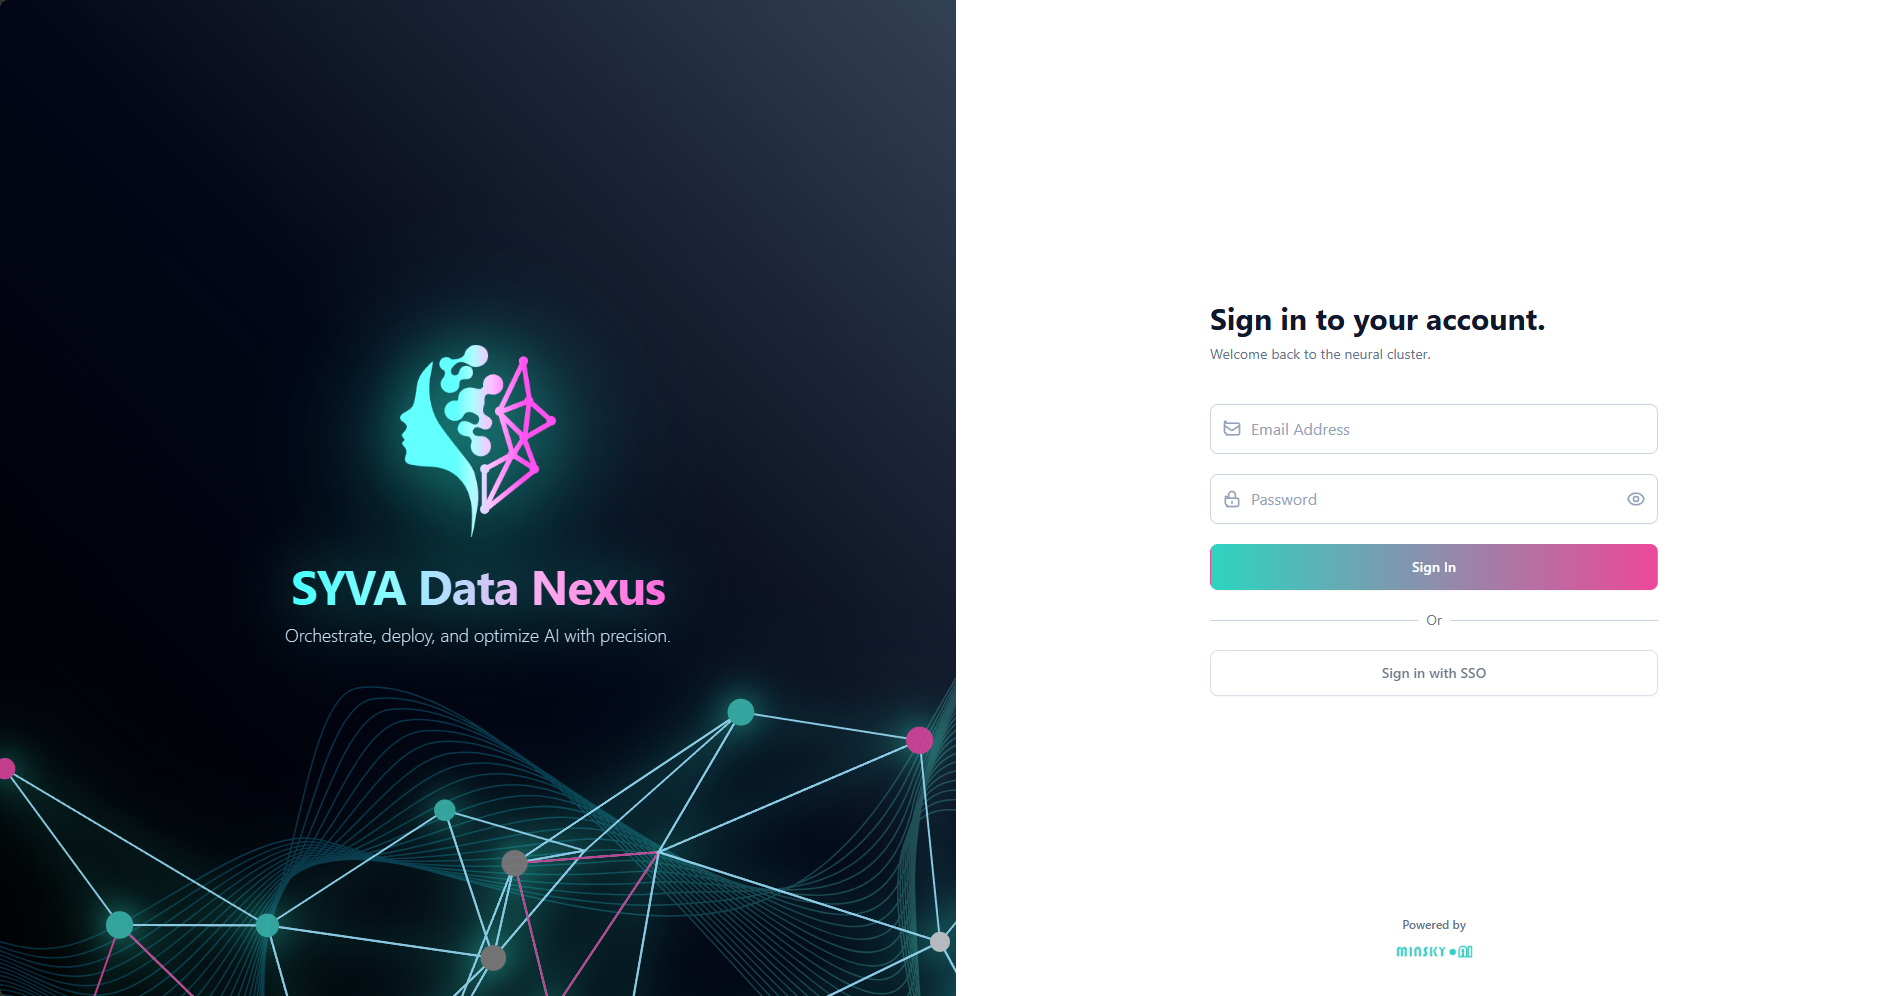
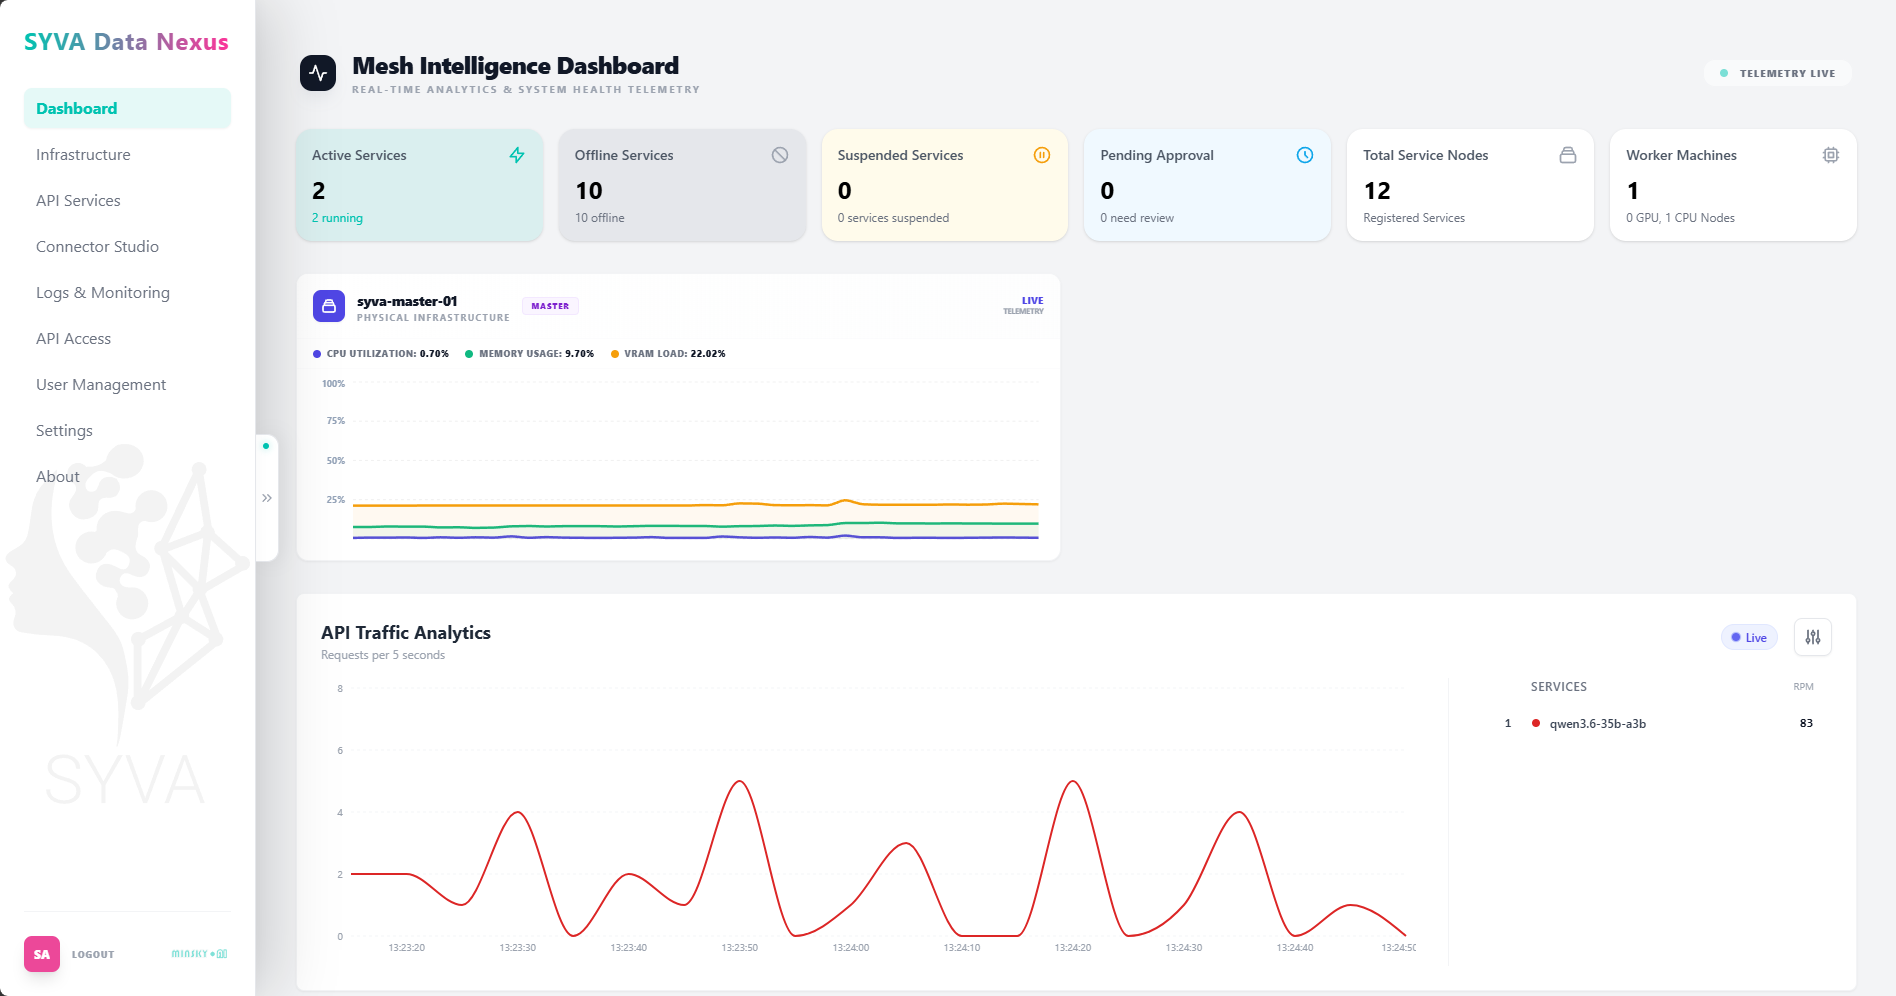
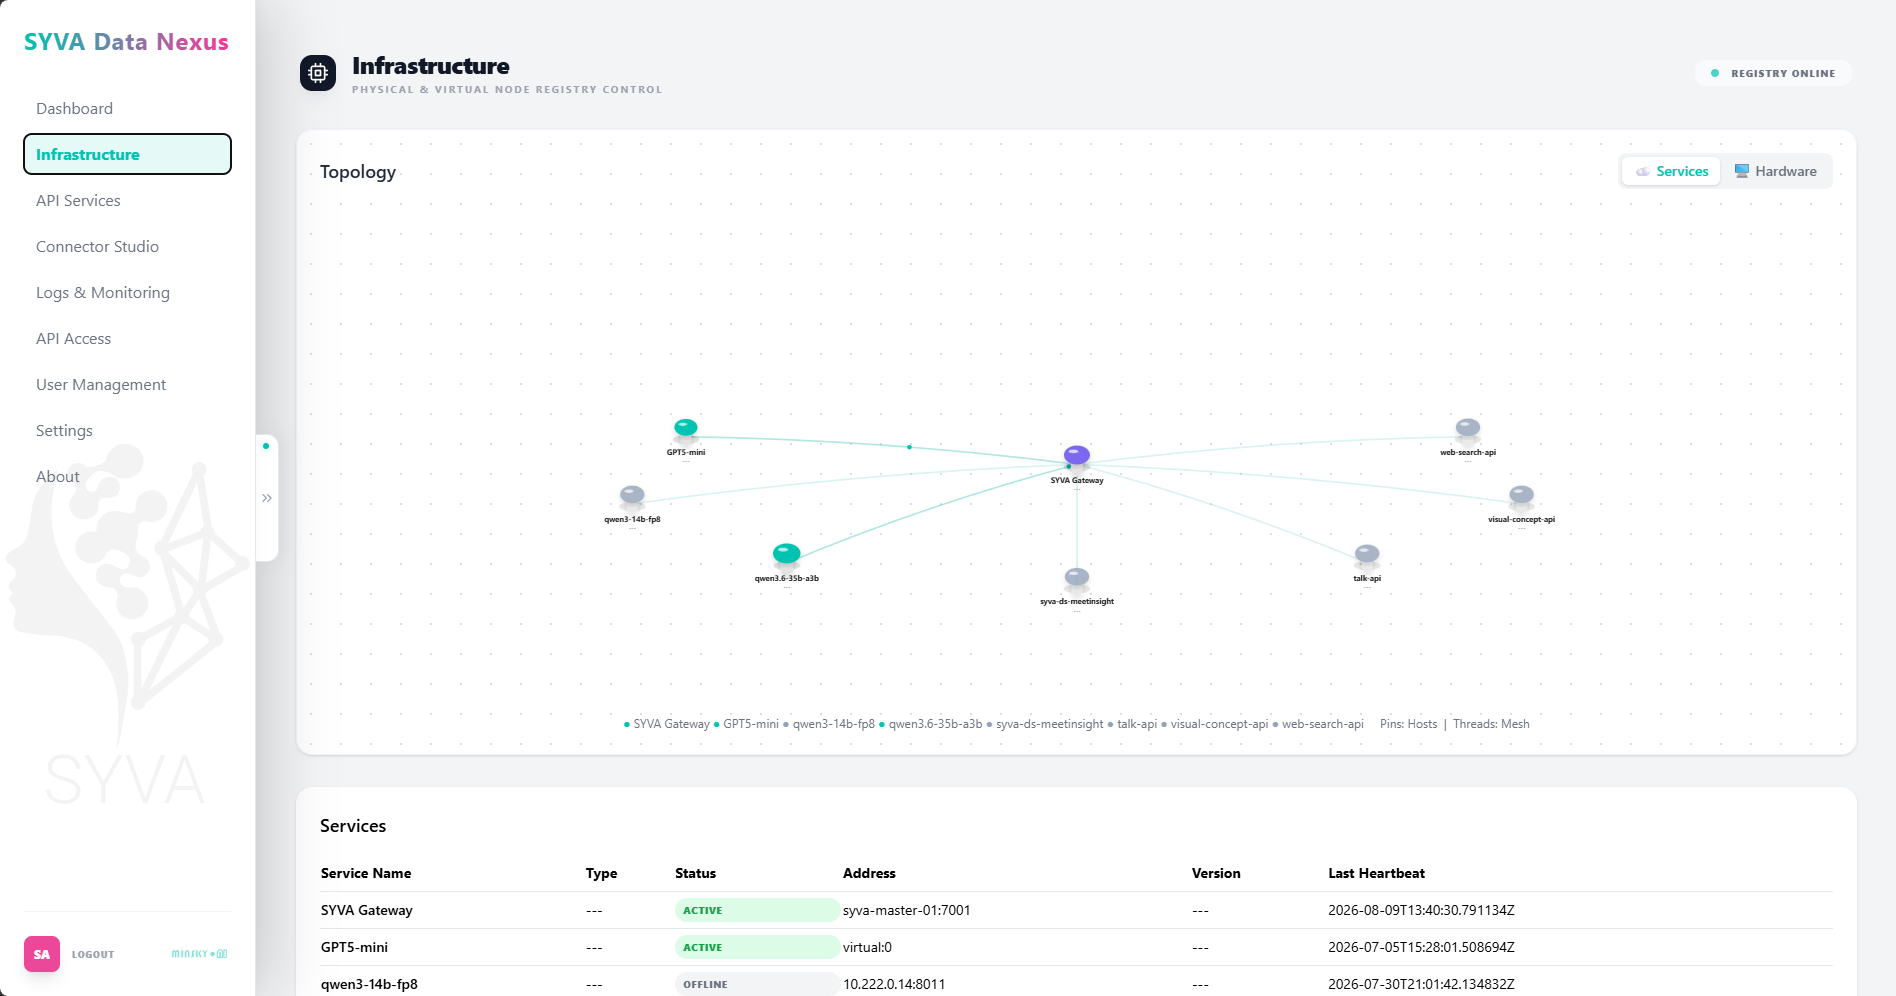
Sign-in, mesh health, topology, and live gateway traffic — enough to see the plane, not a full product tour.
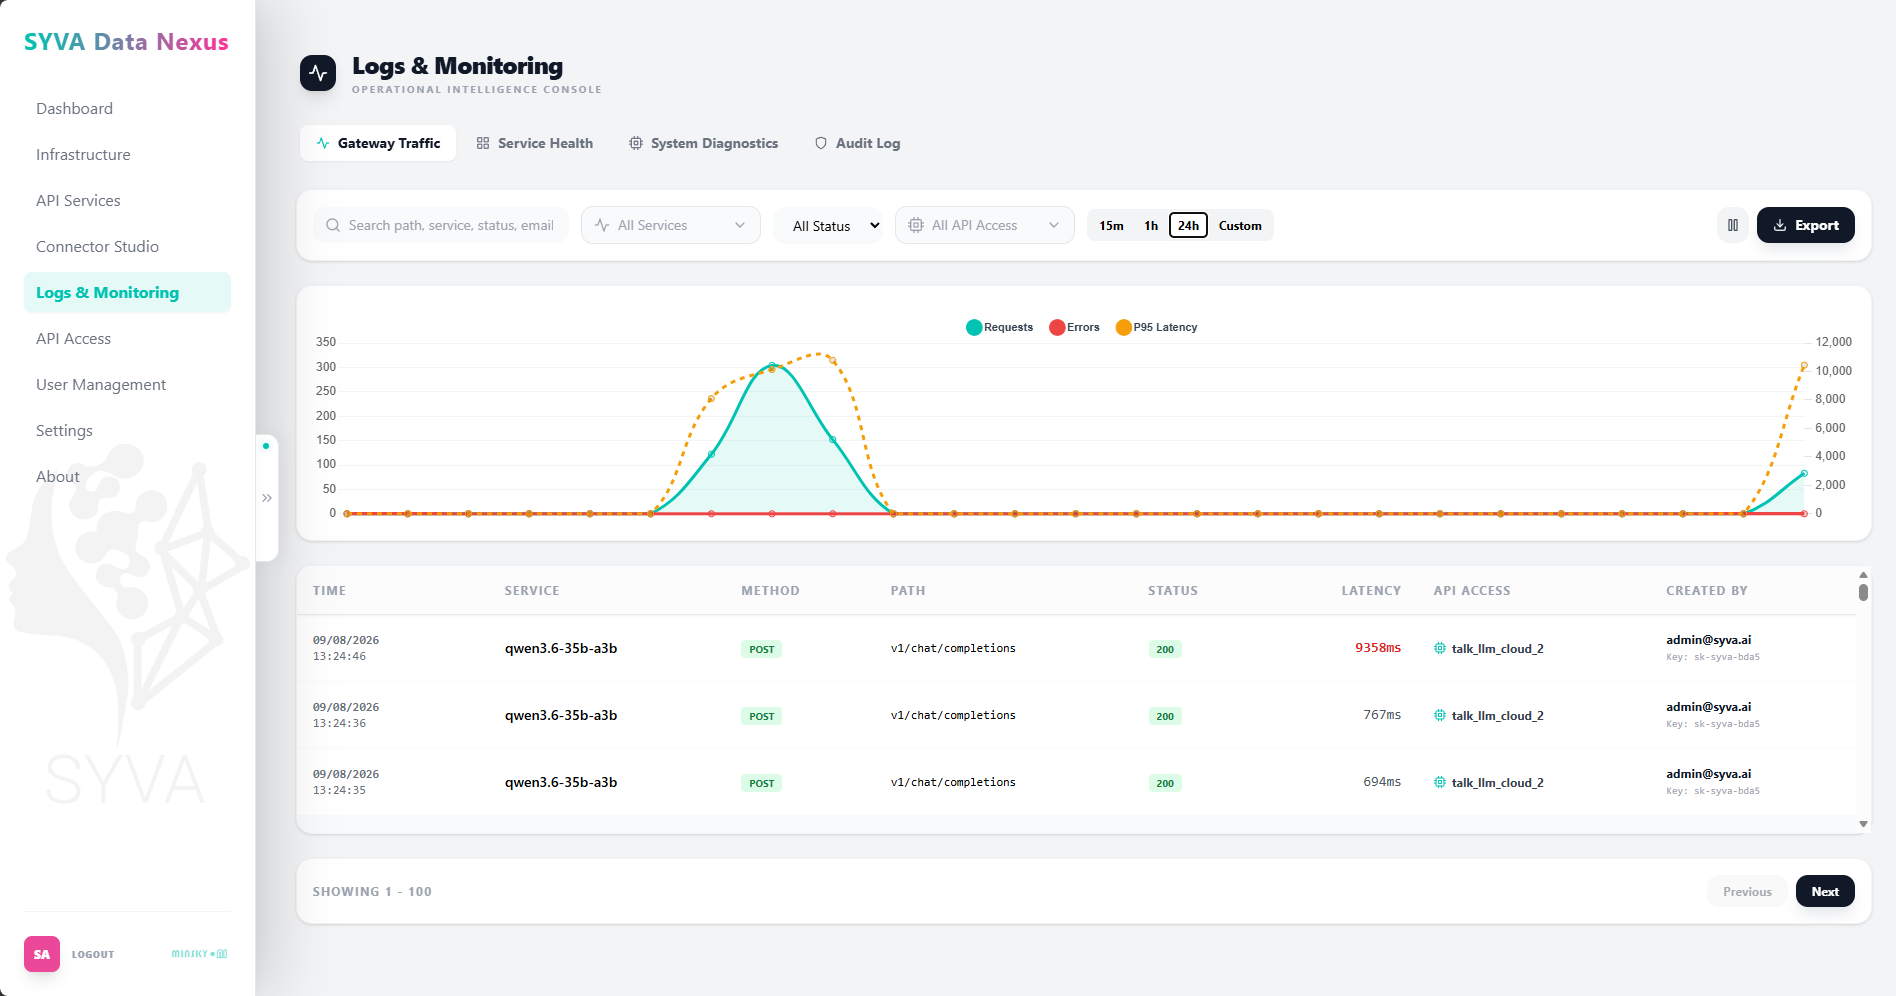
01 / 04
Sign in
Governed access to the private control plane.
Next conversation
See the deeper architecture privately
Public pages stay at the story. In a review we map protocols, deployment, and a pilot path for your estate — without publishing the manual.